
In short
Model Router series · Part 5 of 6 · Start from Part 1 · All parts ↓
Part 4 ended with a route that is a single bet. This part adds a safety net, one layer at a time, and tests it by breaking things on purpose.
- Every layer is a new price, so every layer needs a limit. A fallback chain tries the same tier, a second provider, then the next tier up. A cap of four attempts and an escalation budget stop a bad day from becoming the bill.
- A cheap tier may not write. If
gpt-5.4-nanotries to raise a ticket, the turn moves up before the ticket is written. Once a write may have run, the turn is never re-run on another model, whether the check failed or the call errored. If the outcome is unknown, the turn stops with an error.- The cascade never fired on the held-out questions. Zero escalations in 96 runs. Its check reads only the answer text. The question the router loses in Part 4 gives the right number without the handbook search, and no answer check can see that.
Where this fits: part 5 of 6. We replace the executor in the gateway. The next part logs and proves the result.
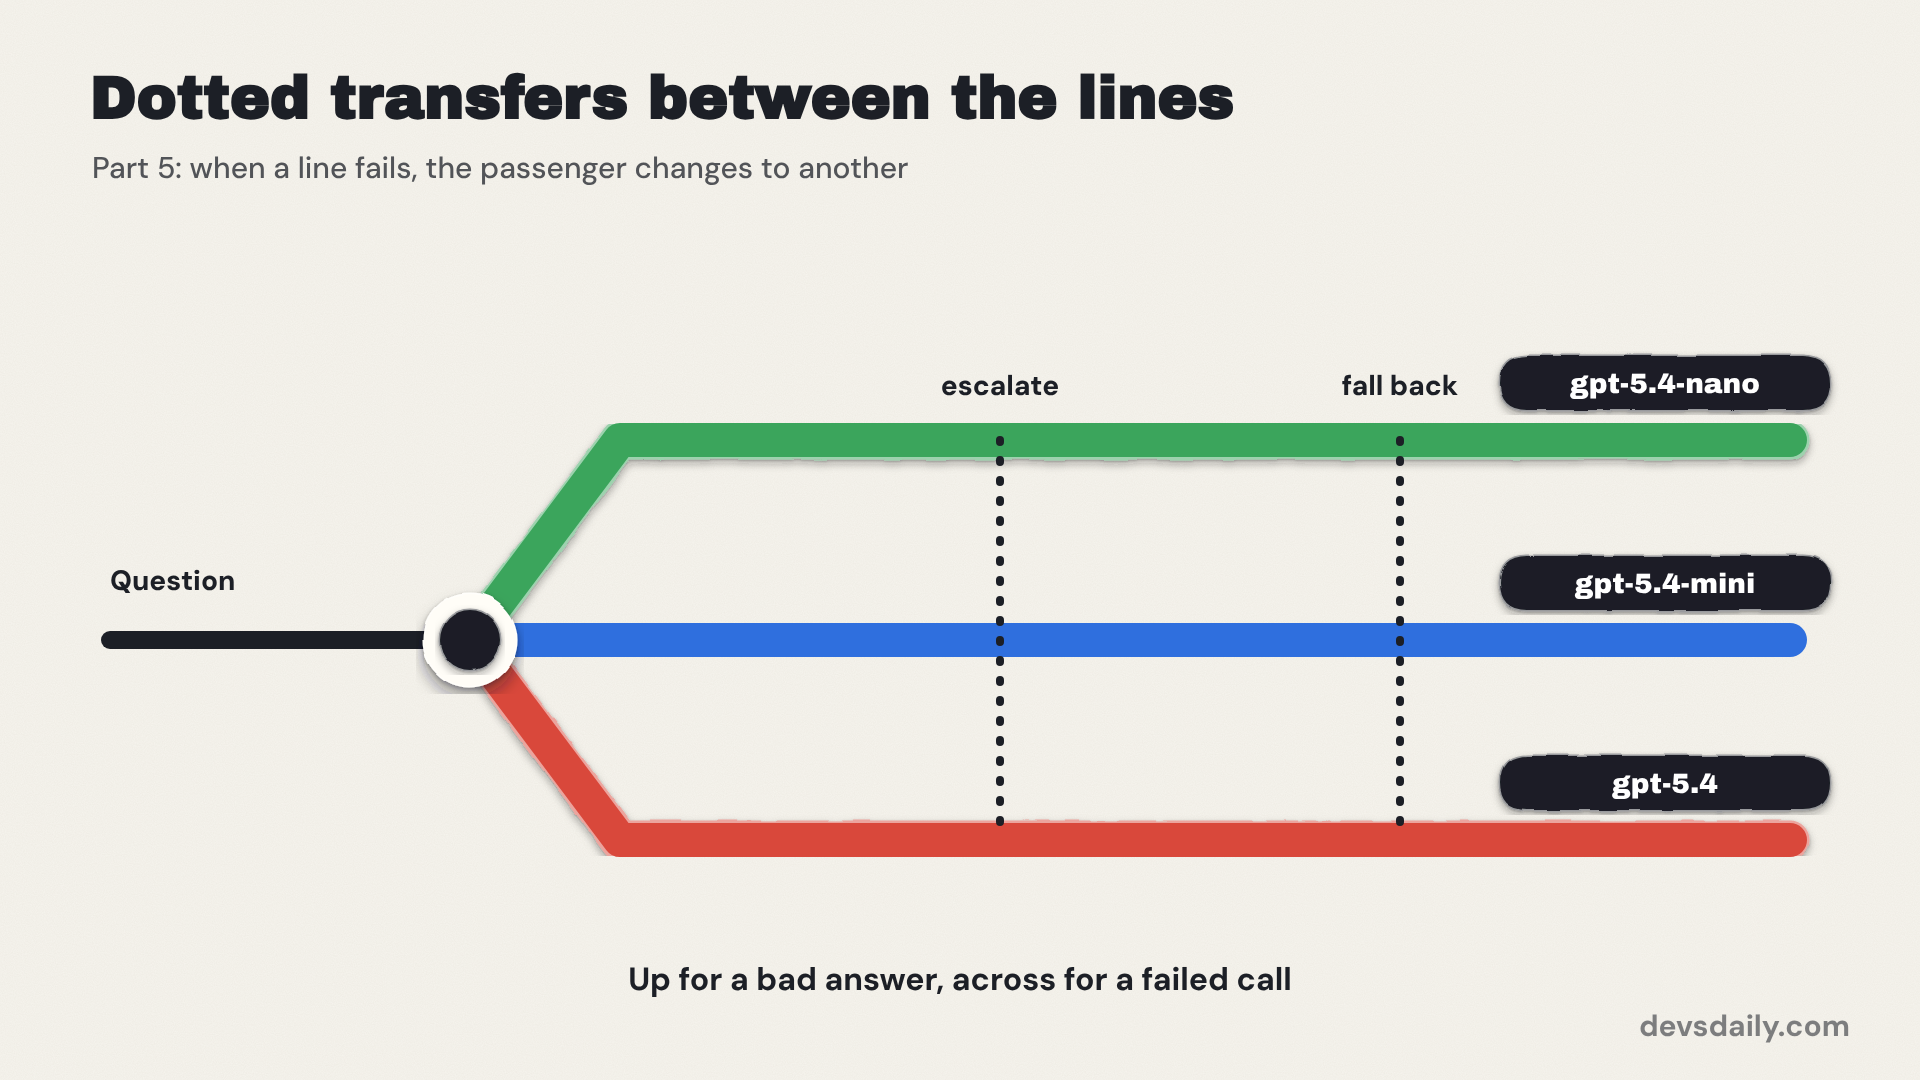
The model the router picks can be slow, rate limited or down, and a cheap model sometimes answers badly. Here is a safety net for both, starting with an LLM fallback to another provider, and then I break things on purpose to see if it holds. One limit up front: I did not run a live second provider. The fallback to another provider is tested with scripted models, and the code path is the same. This layer is insurance, and the held-out test set does not exercise it.
How a routed call fails
Five ways, and each needs a different answer:
- A timeout. The model does not answer in time.
- A rate limit. The provider says slow down.
- A provider error. A 500, or a bad request.
- An empty or broken answer. The model replies, but with nothing useful.
- A wrong route. The router picked a model that cannot do the job.
You already have defence for the first three at the call level. Agents Part 11 sets a 30 second timeout and two retries on every call, and the repo keeps those settings for any provider:
def resilient_factory(spec: str):
    """The Part 11 settings, for any provider: a 30 second call timeout and two retries inside the call."""
    return get_model(spec, timeout=30, max_retries=2)
From router/resilience.py.
What is new is what happens after those retries run out, and what to do about the last two failure types.
LLM fallback to another provider
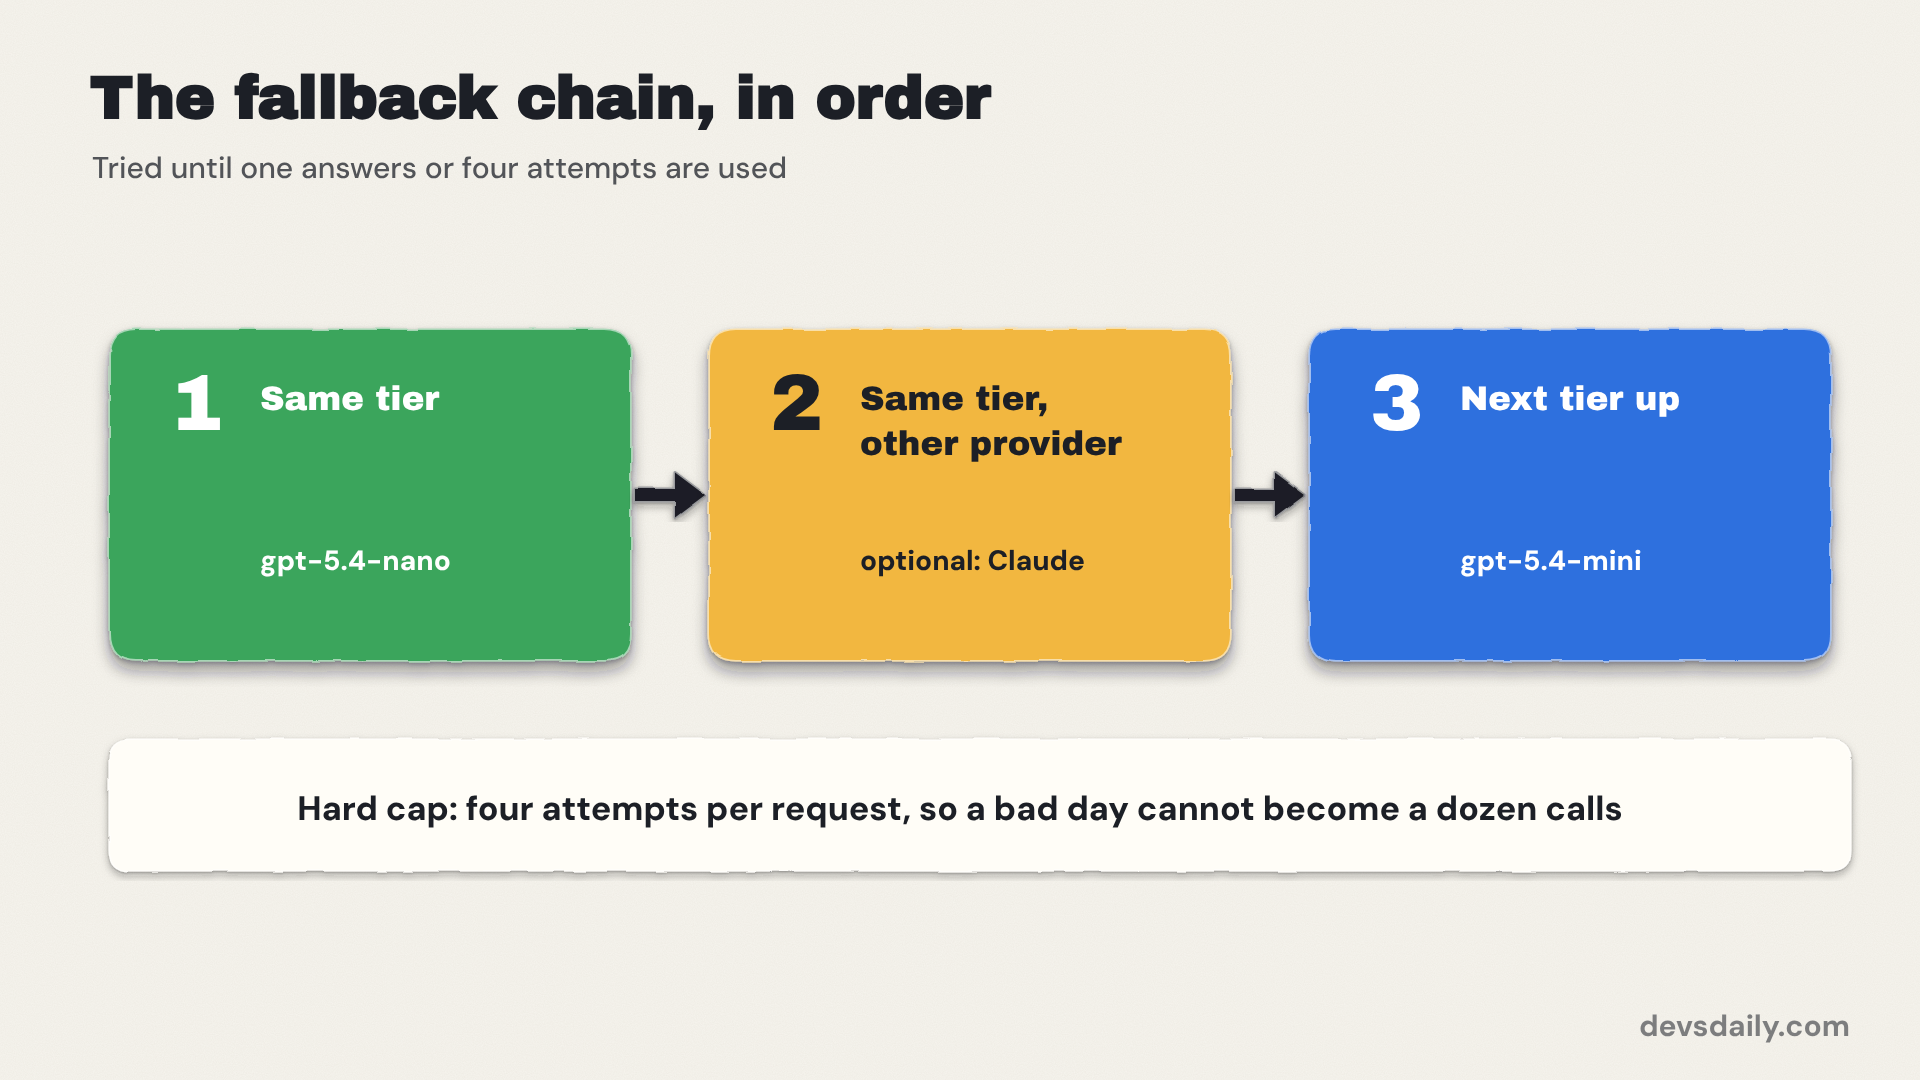
If a model fails, the executor tries the next one in a short chain: the routed model, then the same tier at a second provider if you have one, then the next tier up.
    def chain(self, gateway: Gateway, tier: str) -> list[tuple[str, str]]:
        """Models to try for a tier, in order: the tier itself, the same tier at another provider,
        then the next tier up. Each item is (spec, tier)."""
        chain = [(gateway.catalog.tier_spec(tier, gateway.provider), tier)]
        if self.second_provider:
            other = "anthropic" if gateway.provider == "openai" else "openai"
            chain.append((gateway.catalog.tier_spec(tier, other), tier))
        if up(tier) != tier:
            chain.append((gateway.catalog.tier_spec(up(tier), gateway.provider), up(tier)))
        return chain

    def _attempt(self, gateway: Gateway, spec: str, tier: str, messages: list) -> _Attempt:
        guard = TIER_ORDER.index(tier) < TIER_ORDER.index(self.write_tier)
        ran: list = []
        tools = block_writes(TOOLS) if guard else record_writes(TOOLS, ran)
        with get_usage_metadata_callback() as usage:
            try:
                out = build_agent(gateway.model_factory(spec), tools=tools).invoke({"messages": messages})["messages"]
            except EscalateBeforeWrite:
                return _Attempt("blocked-write", usage=usage.usage_metadata)
            except Exception as exc:  # timeouts, rate limits, provider errors, bad requests
                err = f"{type(exc).__name__}: {exc}"[:200]
                if ran:   # a write may have run, so the outcome is unknown: do not try another model
                    return _Attempt("error-after-write", usage=usage.usage_metadata, error=err)
                return _Attempt("error", usage=usage.usage_metadata, error=err)
        return _Attempt("ok", out, usage.usage_metadata)
From router/resilience.py.
A hard limit on attempts, four by default, covers all of it. Without a limit, a cascade of fallbacks on a bad day can turn one request into a dozen calls.
The second provider is optional, and it comes with two cautions. Claude Sonnet 5.5 is priced close to gpt-5.4, not gpt-5.4-mini, so as a fallback behind mid it is a step up in cost. Test the fallback model on your own question set before you trust it. And a second provider is a second processor of your HR data. Check that your policies allow it. Two providers also means two output formats, which LangChain handles in one adapter.
The cascade
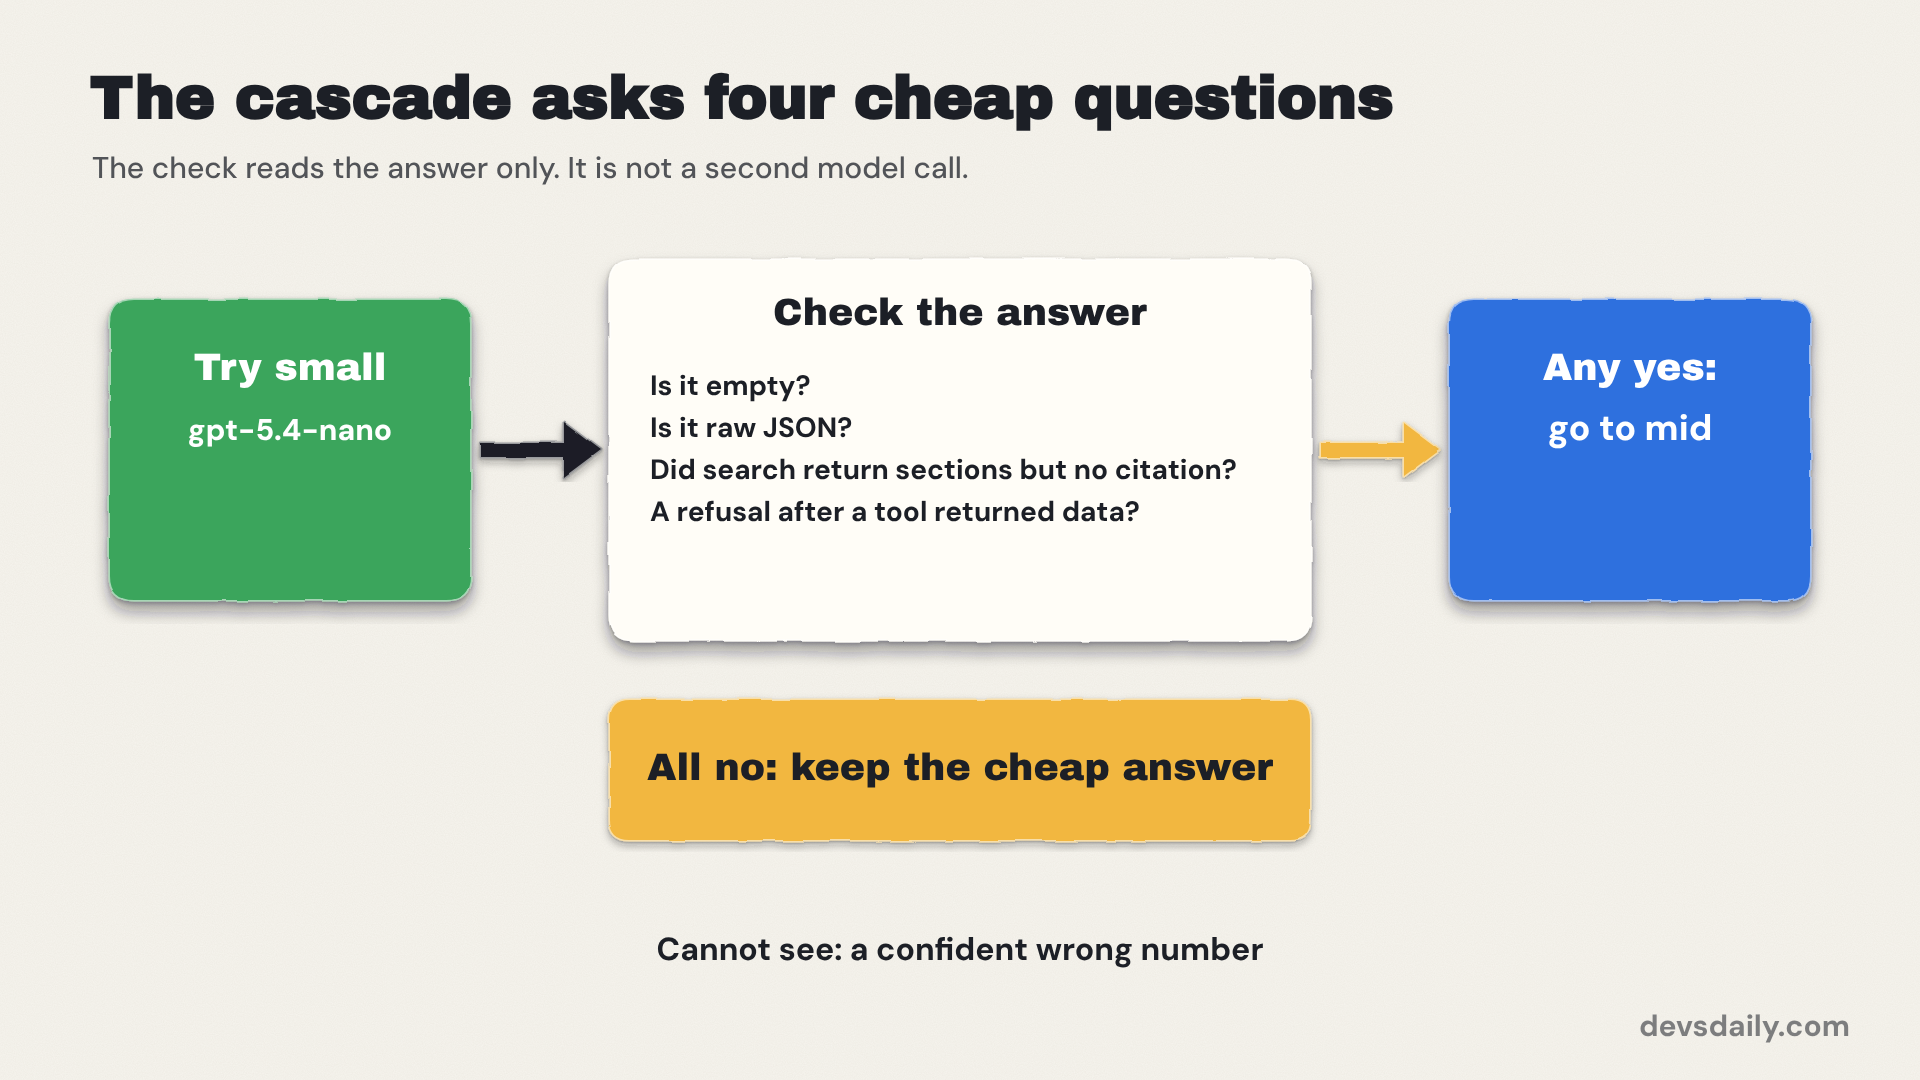
A cascade tries the cheap model first and escalates only if a cheap check says the answer is bad. The check looks only at the answer. It is not a second model call.
def check_answer(messages: list) -> list[str]:
    """Cheap checks on a finished turn. Returns the reasons it failed, or an empty list.

    1. The answer is not empty.
    2. The answer is not raw JSON or a tool dump.
    3. If the handbook search returned sections, the answer cites one in square brackets.
    4. The model did not refuse after a tool had already returned the data.
    The model's own "low confidence" is not used. It has not been shown to track correctness.
    """
    if not messages:
        return ["no messages"]
    last = messages[-1]
    text = last.content if isinstance(last.content, str) else str(last.content)
    failures = []
    if not text.strip():
        failures.append("empty answer")
    if text.lstrip().startswith(("{", "[{")):
        failures.append("answer is raw JSON")
    calls = [c["name"] for m in messages if m.type == "ai" for c in m.tool_calls]
    found_sections = any(m.type == "tool" and '"section"' in m.content for m in messages)
    if "search_policy" in calls and found_sections and not re.search(r"\[[^\]]+\]", text):
        failures.append("handbook searched but no section cited")
    got_data = any(m.type == "tool" and '"ok": false' not in m.content.lower() and '"results": []' not in m.content
                   for m in messages)
    if got_data and REFUSAL.search(text):
        failures.append("refused although a tool returned data")
    return failures
From router/resilience.py.
One check I left out on purpose: the model’s own “I’m not sure”. Nothing shows it tracks whether the answer is right.
What it cannot do: see a confident wrong number. A cascade only catches the failures its check can see.
A cheap tier must not write
This is the rule I would defend hardest. If a cheap model is about to raise a ticket, and a quality check then fails, escalating would run the whole turn again on a bigger model, and the bigger model might raise a second ticket. An idempotency key does not rescue you, because a second model may call the tool with different arguments.
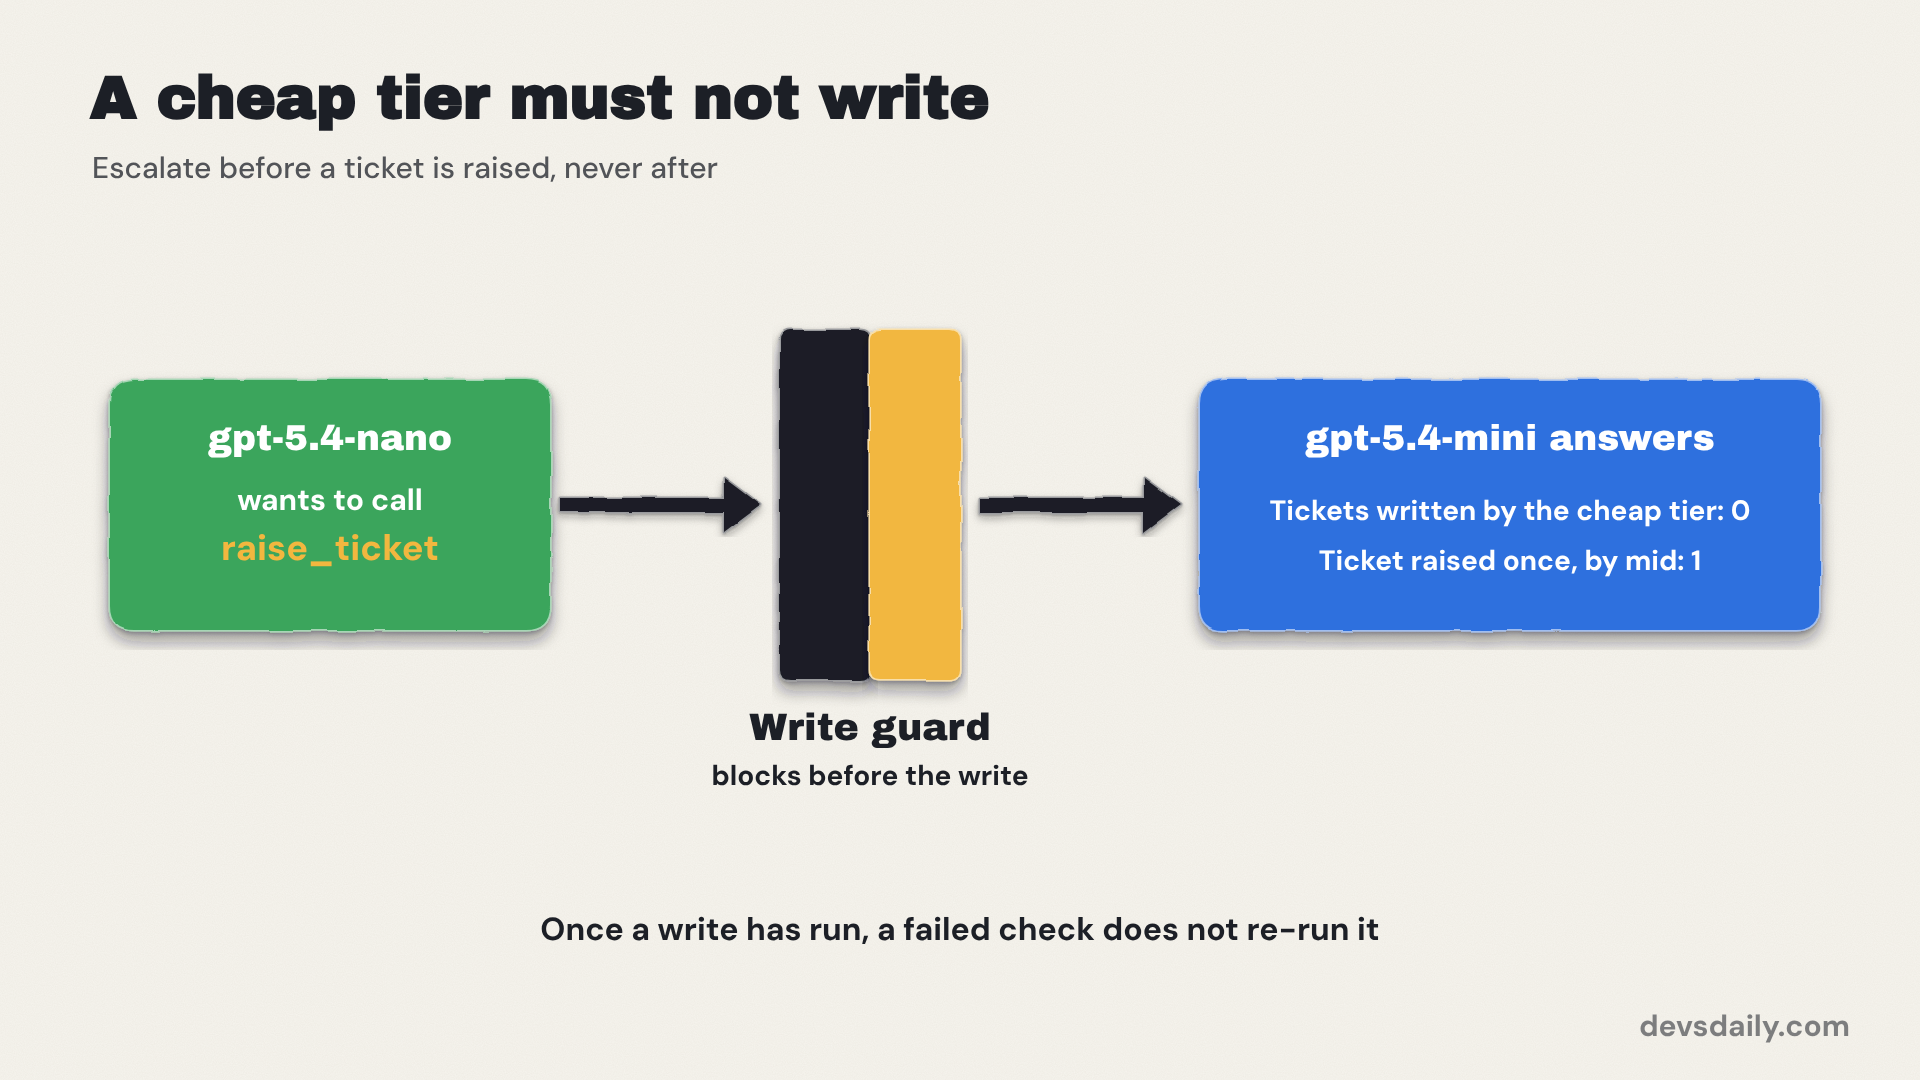
So the cheap tiers get a version of the tools where the write tool raises instead of running:
def block_writes(tools: list, write_names=WRITE_TOOLS) -> list:
    """The same tools, except write tools raise EscalateBeforeWrite instead of running."""
    def blocked_version(tool):
        def refuse(**kwargs):
            raise EscalateBeforeWrite(tool.name)
        return StructuredTool.from_function(func=refuse, name=tool.name, description=tool.description,
                                            args_schema=tool.args_schema)
    return [blocked_version(t) if t.name in write_names else t for t in tools]
From router/resilience.py.
When it fires, the turn moves up a tier before anything is written. And once a write may have run, the turn is never re-run on another model. A failed check does not re-run it. An error does not either. My first version of the executor got the error case wrong. If a mid model raised a ticket and the next call timed out, the chain treated it as a failed attempt and tried the next model, and when that model worded the ticket differently, two tickets existed. The write tools now note that they were called, so an exception after a write stops the turn with an error instead of a retry. The outcome of that write is unknown, and the right next step is to look it up, not to ask another model. A real backend should also take an idempotency key per request, and keep the write behind the approval and security controls from Agents Part 7 and Part 10. Scenario 6b in the script shows it.
A budget for escalations
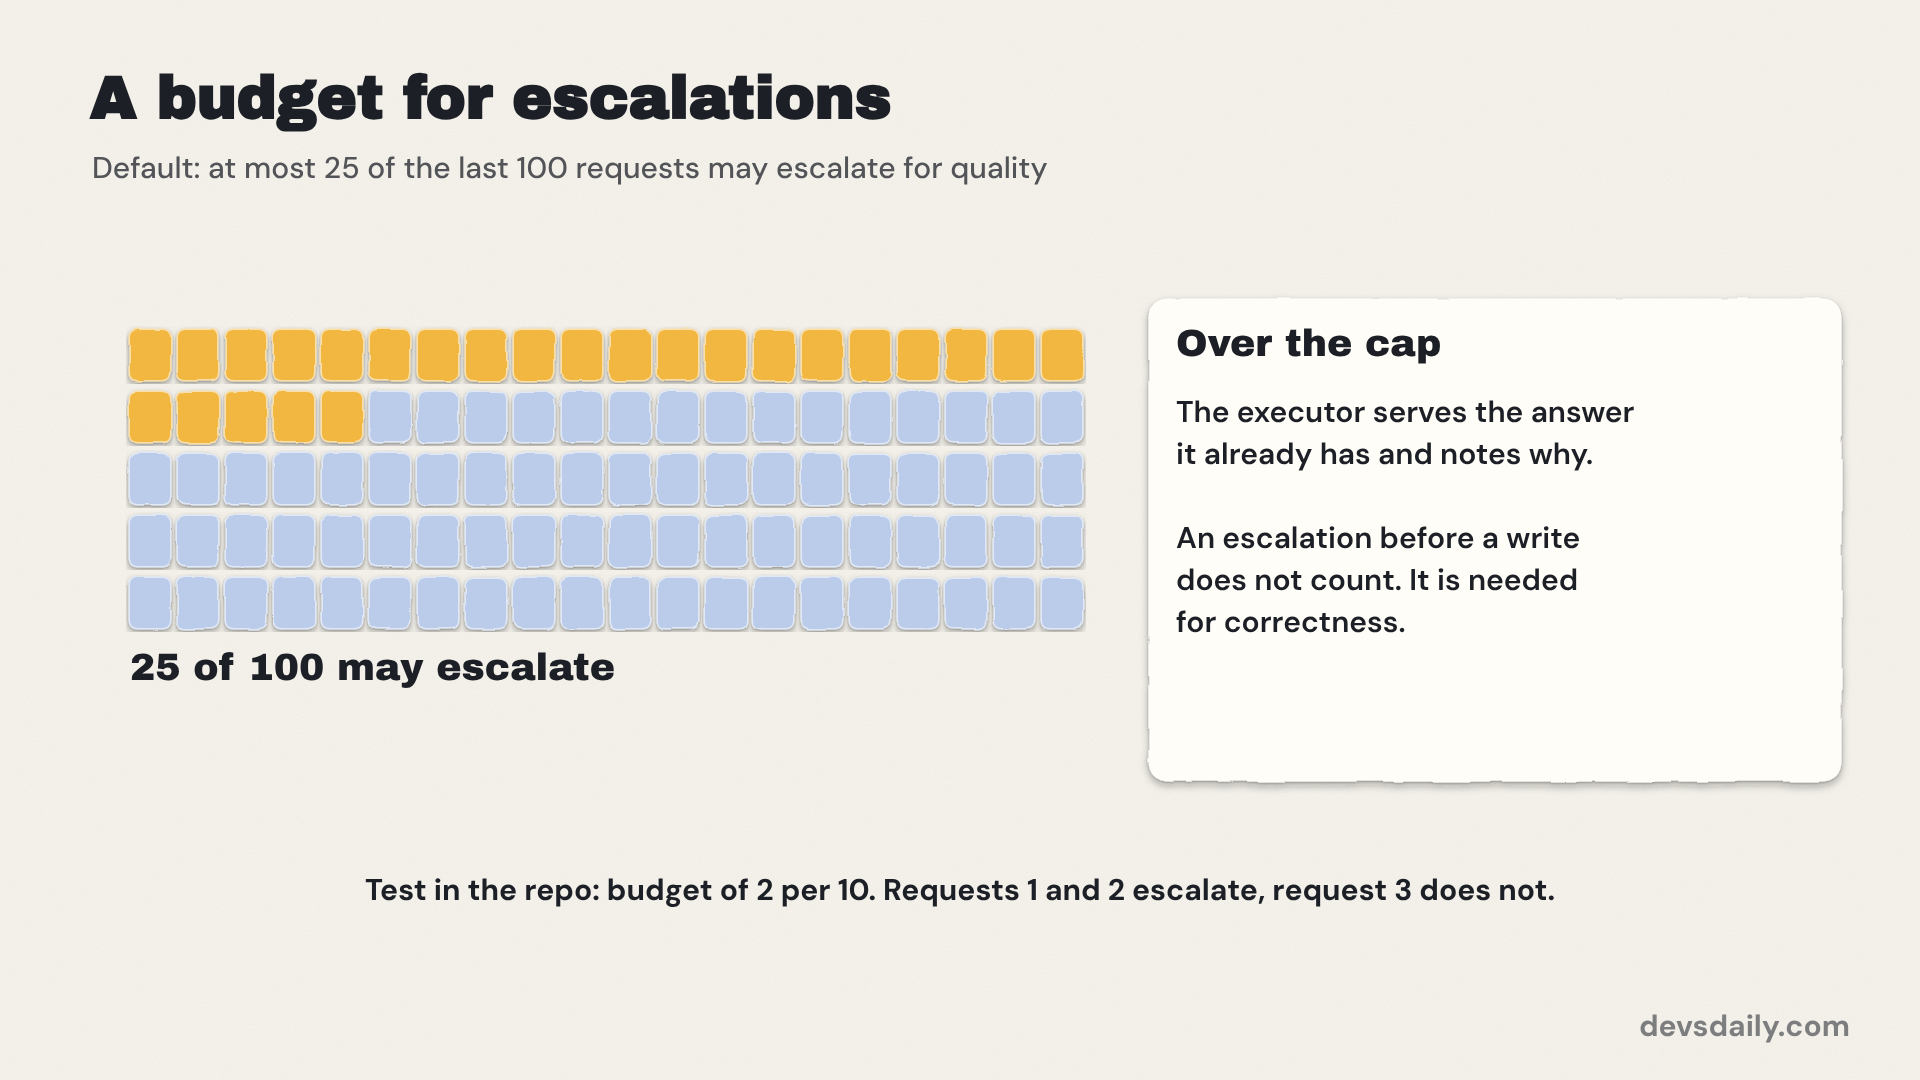
On a bad day the cheap model might fail the check on most requests. Every one would escalate, and you would silently be paying for the large model on everything. An escalation budget caps that:
class EscalationBudget:
    """At most max_rate of the last `window` requests may escalate for quality reasons.

    Escalating before a write is not counted: it is needed for correctness, not a choice.
    """

    def __init__(self, max_rate: float = 0.25, window: int = 100):
        self.max_escalations = max_rate * window
        self.recent: deque[bool] = deque(maxlen=window)

    def allow(self) -> bool:
        return sum(self.recent) < self.max_escalations

    def record(self, escalated: bool) -> None:
        self.recent.append(escalated)

    @property
    def used(self) -> int:
        return sum(self.recent)
From router/resilience.py.
The default is 25 percent of the last 100 requests. Past that, the executor serves the answer it has and notes why.
Here is the executor that ties it together:
    def __call__(self, gateway: Gateway, route: Route, messages: list) -> Outcome:
        usage: dict = {}
        attempts: list[dict] = []
        tier, escalated, quality = route.tier, False, False   # quality: an escalation the budget pays for
        while True:
            result = None
            for spec, spec_tier in self.chain(gateway, tier):
                if len(attempts) >= self.max_attempts:
                    break
                a = self._attempt(gateway, spec, spec_tier, messages)
                usage = merge_usage(usage, a.usage)
                attempts.append({"spec": spec, "tier": spec_tier, "ok": a.status == "ok", "status": a.status,
                                 "error": a.error})
                if a.status == "error-after-write":
                    attempts[-1]["note"] = "a write may have run, so no other model is tried"
                    break
                if a.status != "error":
                    result, tier = a, spec_tier
                    break
            if result is None:
                self.budget.record(quality)
                return Outcome([], usage, attempts, escalated,
                               error=(attempts[-1]["error"] or "attempt limit reached") if attempts else "no attempts allowed")
            if result.status == "blocked-write":
                tier, escalated = up(tier), True     # needed for correctness: not charged to the budget
                attempts[-1]["note"] = "cheap tier tried to write, moved up before the write ran"
                continue
            problems = self.check(result.messages) if self.cascade else []
            if not problems:
                self.budget.record(quality)
                return Outcome(result.messages, usage, attempts, escalated)
            attempts[-1]["check_failed"] = problems
            if wrote(result.messages):
                attempts[-1]["note"] = "a write already ran, so this turn is not re-run"
            elif tier == "large" or len(attempts) >= self.max_attempts:
                attempts[-1]["note"] = "no higher tier or attempt left"
            elif not self.budget.allow():
                attempts[-1]["note"] = "escalation budget used up, serving this answer"
            else:
                tier, escalated, quality = up(tier), True, True
                continue
            self.budget.record(quality)
            return Outcome(result.messages, usage, attempts, escalated)
From router/resilience.py.
One cost to know about. A check after the answer breaks the token-by-token streaming from Agents Part 11, because you cannot check an answer you have not finished receiving. If you stream to users, run the check on the finished answer and accept that an escalation shows up as a longer wait.
Break it on purpose
Hoping the safety net works is not testing it. The check script has eight scripted failures. A fake model fails on command, so you need no key.
python -m scripts.check_p5_failures| What goes wrong | What happens | Escalated | Tickets written |
|---|---|---|---|
| The primary model times out, a second provider is set | gpt-5.4-nano errors, claude-haiku-5-5 answers | no | 0 |
| The primary times out, no second provider | gpt-5.4-nano errors, gpt-5.4-mini answers | no | 0 |
| Every model fails | Both models fail, the turn stops and reports TimeoutError | no | 0 |
| The cheap model returns an empty answer | Check fails, mid answers | yes | 0 |
| The cheap model tries to raise a ticket | Blocked before the write, mid answers | yes | 1 |
| A write already ran and the check fails | Not re-run | no | 1 |
| A write ran, then the model errors | gpt-5.4-mini errors after the write, no other model is tried, the turn reports TimeoutError | no | 1 |
| The check fails on every request, budget of 2 per 10 | Requests 1 and 2 escalate, request 3 does not |
The ticket count in the fifth row is the point. The cheap model was stopped before the write, mid wrote the single ticket, and the count is one, not two. The sixth row shows the other half: the turn already wrote, the check failed, and nothing re-ran. The seventh row is the error case: the model failed after the write, and the turn stopped with one ticket.
The last row shows the budget doing its job. Request 3 printed “escalation budget used up, serving this answer”.
These are scripted models, so they prove the wiring. The rejected answer in the fourth row is scripted too: no real model answer failed the check in any run. They say nothing about how a real model behaves. For that, the script also breaks the primary model for one real question. I made gpt-5.4-nano fail with a simulated timeout on “How many earned leave days do I have?”.
gpt-5.4-nano: error (TimeoutError)  ->  gpt-5.4-mini: ok
cost $0.001137   answer: You have **12 earned leave days** remaining.
The nano attempt failed before using any tokens, so the turn cost what a mid answer costs: $0.001137, the same as the mid price for that question in Part 1. The failure was free in dollars, and the fallback was the price of the tier above. A real timeout would also wait for the client timeout on each try before the fallback runs, and I did not measure that latency.
What the net costs, on the held-out questions
The last section of the check runs the held-out questions through the rules router with the cascade on.
| Setup | Passed | $ per conversation | $ per correct |
|---|---|---|---|
| Rules router (Part 3) | 95 of 96 | $0.00135 | $0.00137 |
| Rules router + cascade | 95 of 96 | $0.00132 | $0.00134 |
Zero of 96 runs escalated. The cascade did nothing, because nothing failed its check.
Now the cost columns. The two rows send every question to the same tiers (24 small, 60 mid, 12 large) and the cascade never fired, yet the cost differs by about 2 percent. That gap is run-to-run variation, since model output and tool use differ a little each time. It is as large as the whole Part 3 saving, so read small differences with care anywhere in this series.
So did the safety net pay for itself? On this traffic it neither cost anything nor saved anything. Its value is insurance: the forced failure moved to a working model, and the write guard stopped a duplicate ticket. Insurance is hard to price from 96 calm runs.
The cascade’s blind spot is easy to name. In Part 4, the router lost three runs on one question, r-earned-8m, where nano gave the right number, “12”, without searching the handbook. A fluent answer with a plausible number passes every check above. The final setup in Part 6 puts this same cascade on top of the classifier, and it again passed 93 of 96 with no escalations. The cascade added nothing there either.
From a test to a log
The wiring holds up. How do we run this, watch it, and prove the number went down? That is Part 6.
Next: Part 6: Prove your LLM router saves money
The series
- Not every prompt needs your biggest model
- How do you know the small model is good enough?
- Your first LLM router is just a few rules
- When the rules run out, let a small model decide
- LLM fallbacks: build the safety net before you need it (this part)
- Prove your LLM router saves money
